

Databricks
Source and destination
Polytomic connects to a specific Databricks warehouse using the server hostname and HTTP path.
To determine the settings for your warehouse, log into your Databricks workspace. In the sidebar, click SQL Warehouses, then click the name of the warehouse you want to use with Polytomic. The Connection details tab contains the server hostname, port, and HTTP path, which you enter in Polytomic.
Polytomic authenticates to Databricks using either:
- OAuth Service Principal (recommended): a service principal with an OAuth secret (OAuth machine-to-machine authentication). See Authenticating with OAuth below.
- Access Token: a personal access token belonging to a user or service principal.
Whichever you use, the identity must have the CAN USE permission on the SQL warehouse (in the warehouse's Permissions settings) and the Unity Catalog privileges listed in Databricks permissions.
Configuring the connection
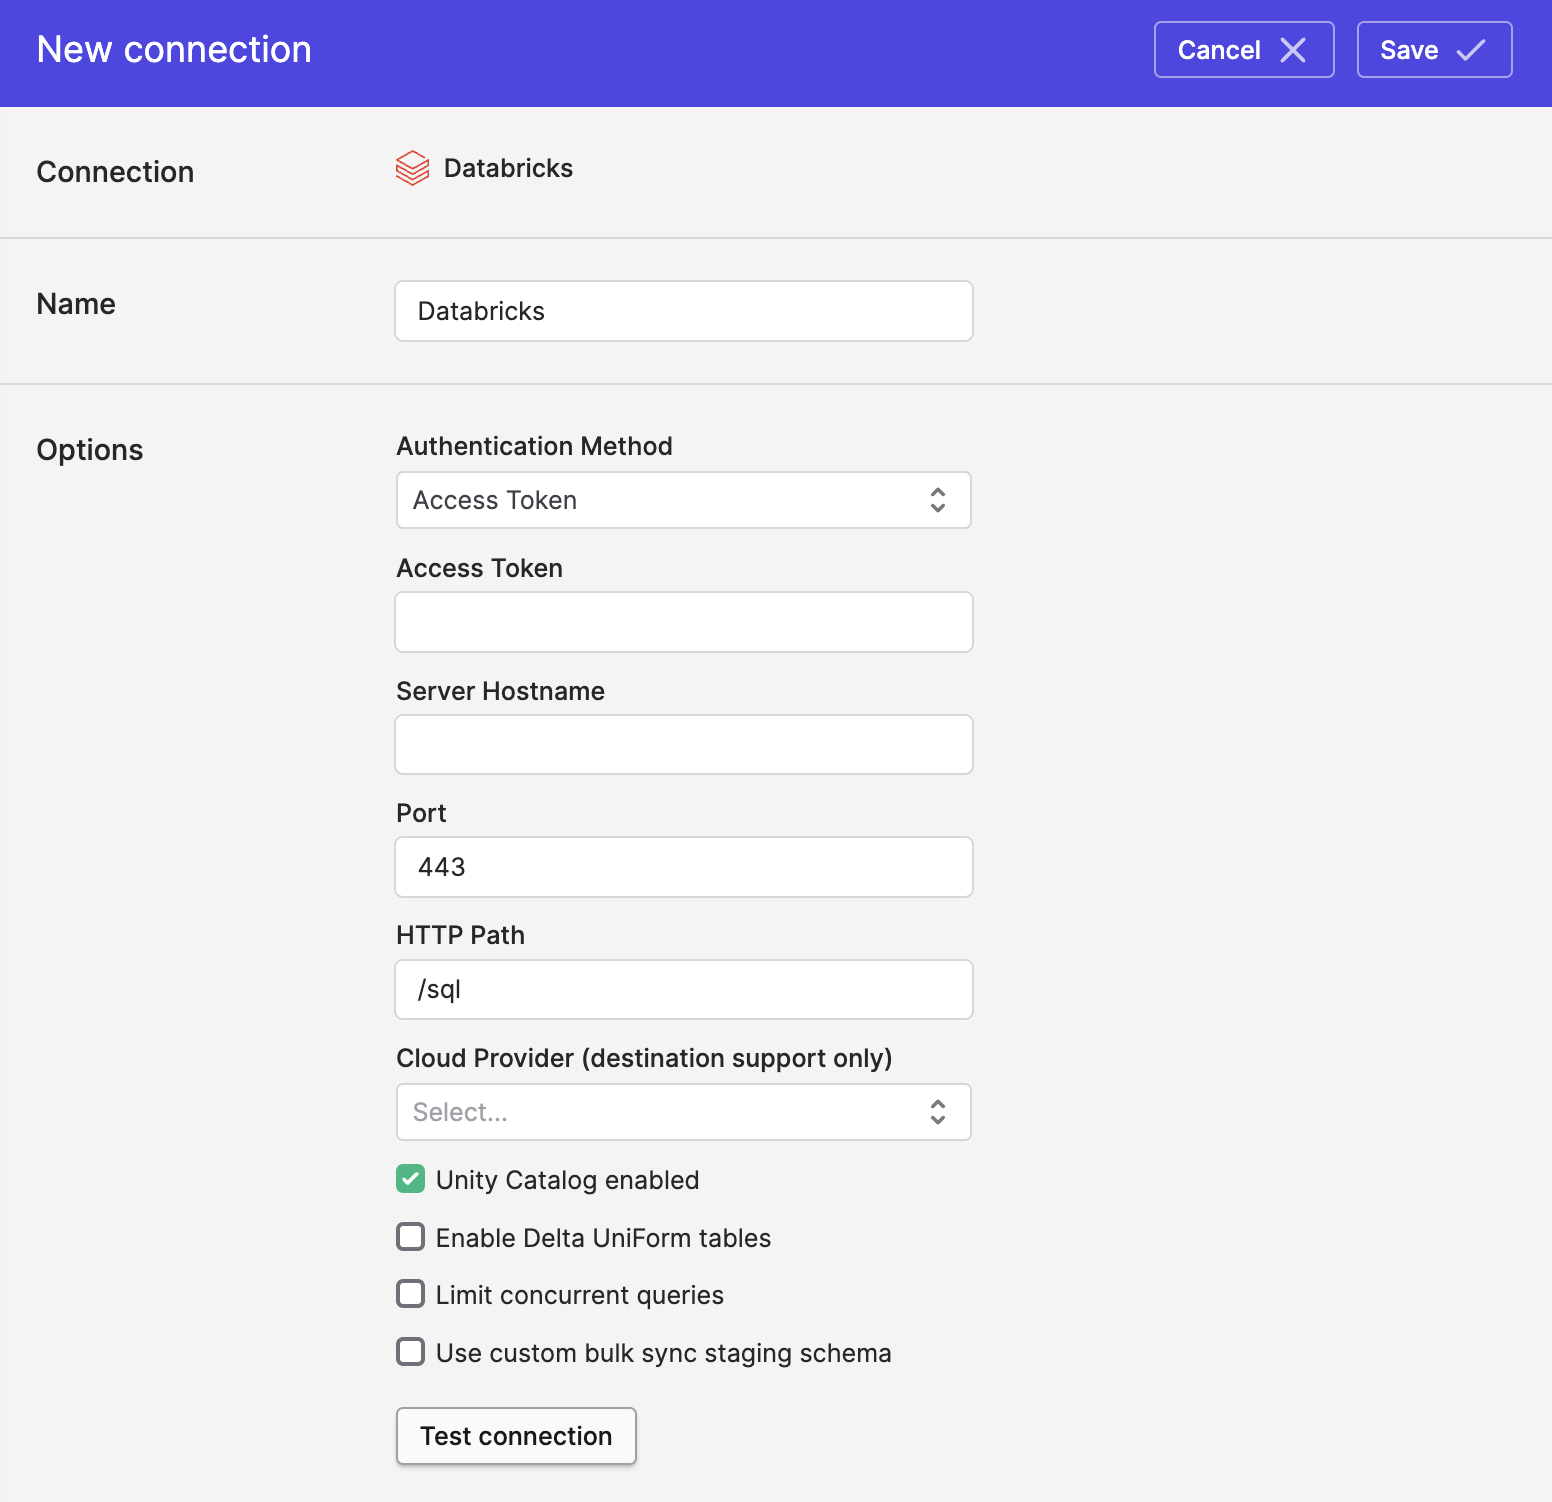
- In Polytomic, go to Connections → Add connection → Databricks.
-
Choose an Authentication method and enter its credentials. For service principals, see Authenticating with OAuth. Then enter the Server hostname, Port, and HTTP path.
-
If your workspace doesn't have Unity Catalog enabled, untick the Unity Catalog enabled checkbox. If it does, you can tick Include legacy Hive metastore tables to also read tables from the workspace's legacy
hive_metastorecatalog. -
Click Save.
Authenticating with OAuth
To use OAuth machine-to-machine authentication:
- In your Databricks account or workspace settings, go to Identity and access → Service principals and add a service principal for Polytomic. If you created it at the account level, also add it to the workspace.
- Open the service principal's Secrets tab and click Generate secret. Copy the Client ID and Secret.
- Grant the service principal CAN USE on the SQL warehouse and the Unity Catalog privileges listed in Databricks permissions.
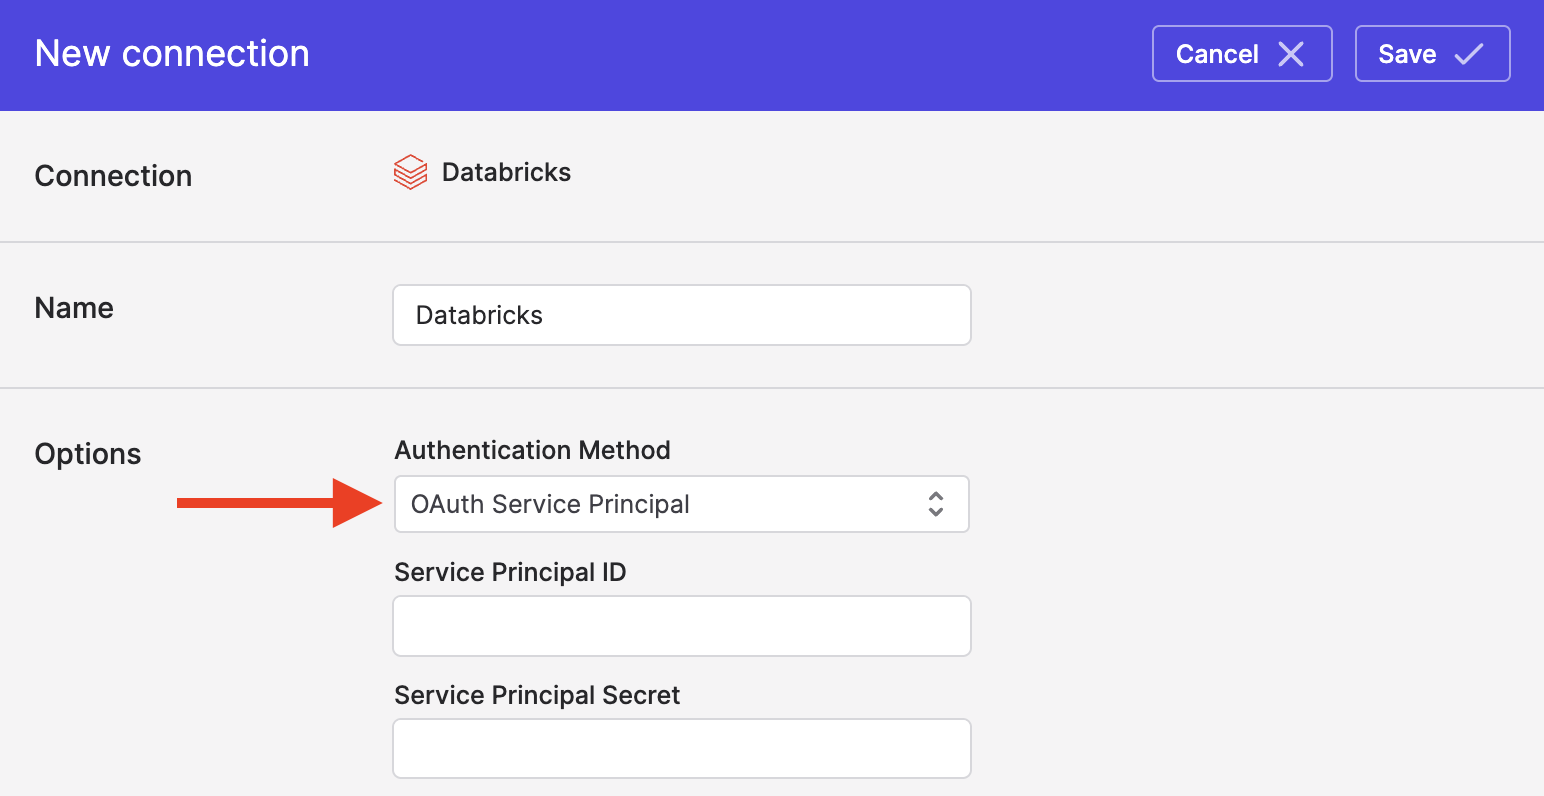
- In Polytomic, set Authentication method to OAuth Service Principal. Enter the client ID as Service principal ID and the secret as Service principal secret.
Writing to Databricks
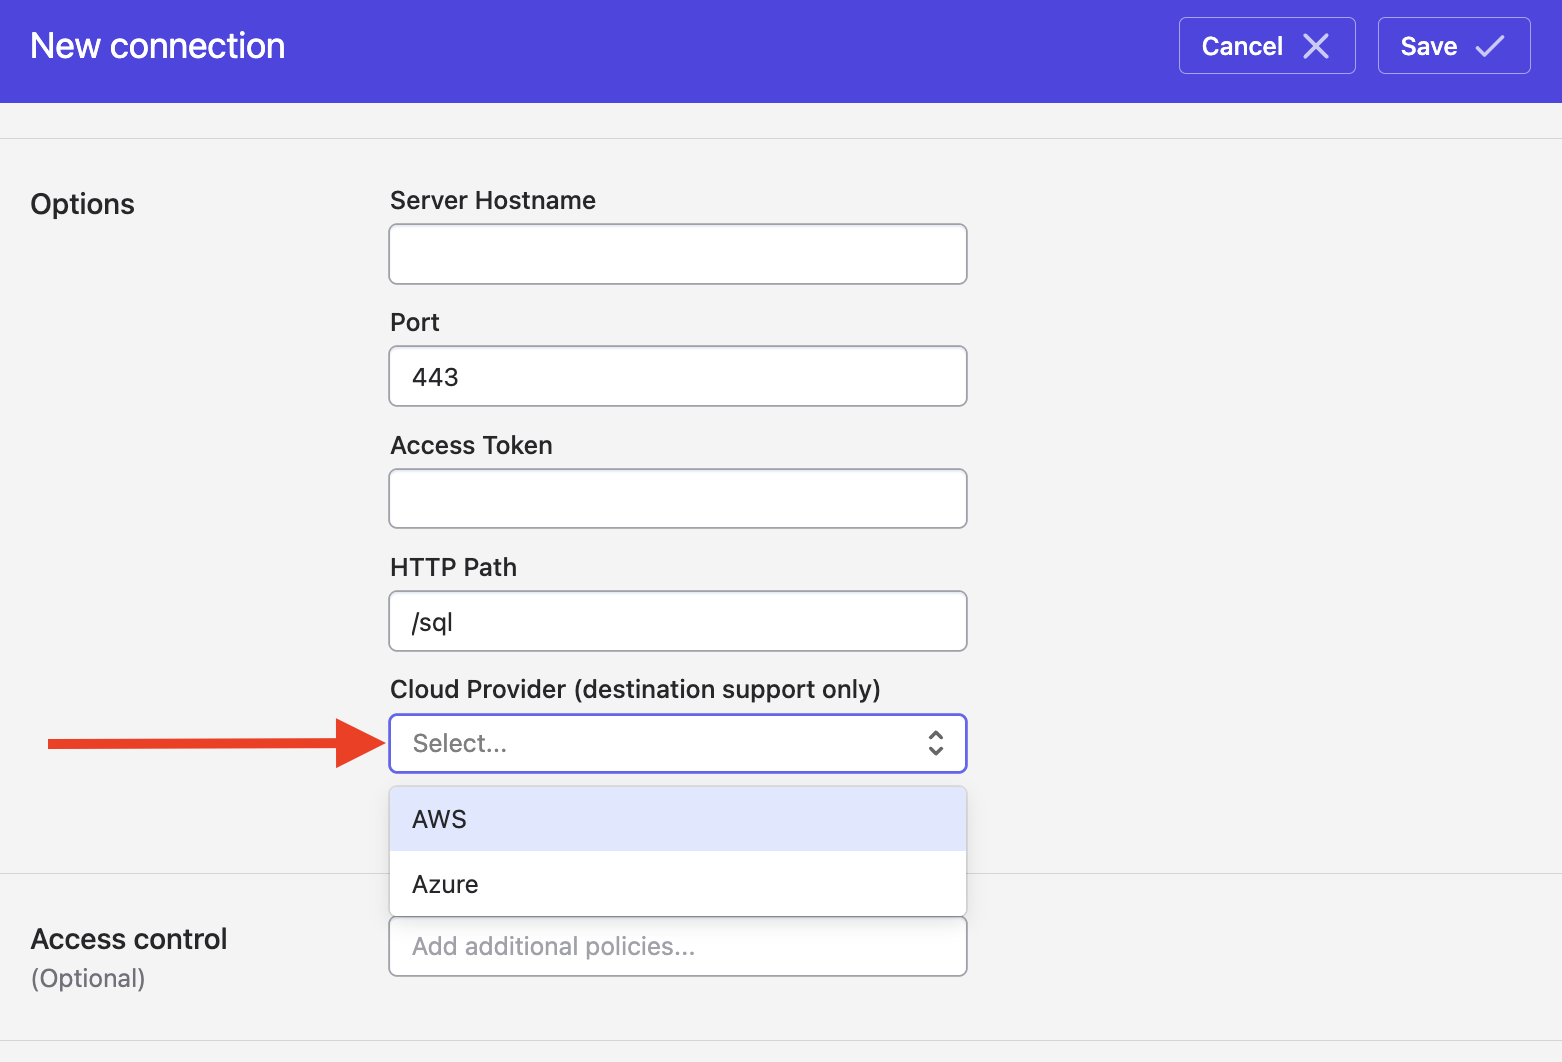
If you'd like to also write to Databricks, you'll need to select your cloud provider and provide its access settings:
Writing to Databricks on AWS
(For connecting to Databricks on Azure, see the next section.)
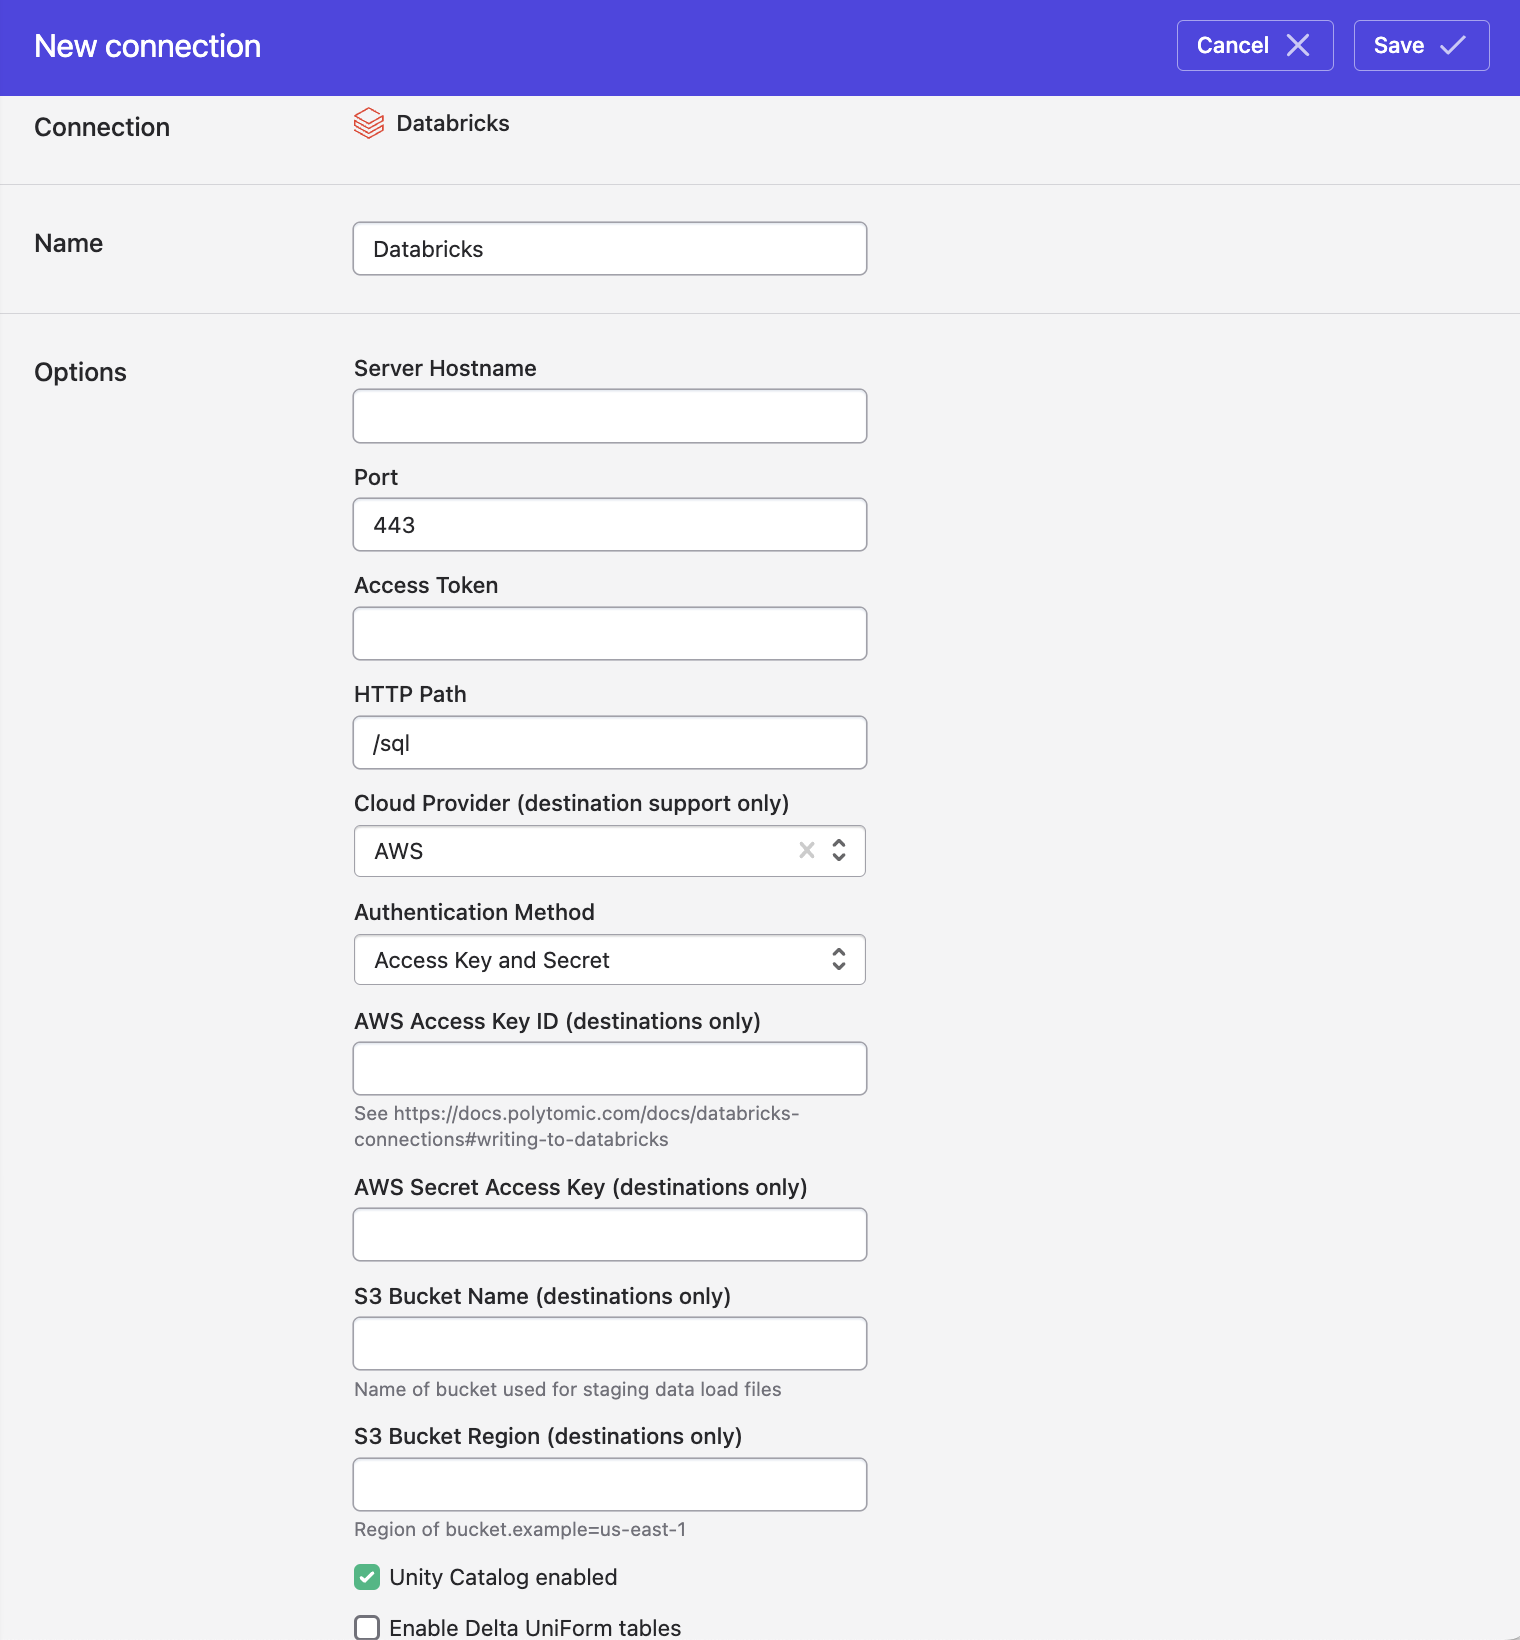
To let Polytomic write to your AWS Databricks workspace, provide the following information:
- S3 bucket name and S3 bucket region (e.g.
us-east-1). Polytomic uses an S3 bucket to stage data for syncs into Databricks. The bucket name may include a prefix, e.g.s3://my-bucket/polytomic. - An AWS authentication method, either:
- Access Key and Secret: an AWS access key ID and secret access key. Polytomic uses these to upload staged files. It also passes the AWS credentials to Databricks in its
COPY INTOstatements, so you don't need a Databricks storage credential. - IAM role: an IAM role ARN that Polytomic assumes when staging data into the bucket. Databricks also needs access to the bucket; see Using an AWS IAM Role to stage data for Databricks.
- Access Key and Secret: an AWS access key ID and secret access key. Polytomic uses these to upload staged files. It also passes the AWS credentials to Databricks in its
The access key's IAM user (or the IAM role) must have this access to the staging bucket:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:DeleteObject",
        "s3:ListBucket",
        "s3:GetBucketLocation",
        "s3:ListBucketMultipartUploads",
        "s3:ListMultipartUploadParts",
        "s3:AbortMultipartUpload"
      ],
      "Resource": [
        "arn:aws:s3:::your-bucket-name",
        "arn:aws:s3:::your-bucket-name/*"
      ]
    }
  ]
}
Using an AWS IAM Role to stage data for Databricks
If you're on AWS and require authenticating using an IAM role rather than an access key and secret, see instructions here.
Writing to Databricks on Azure
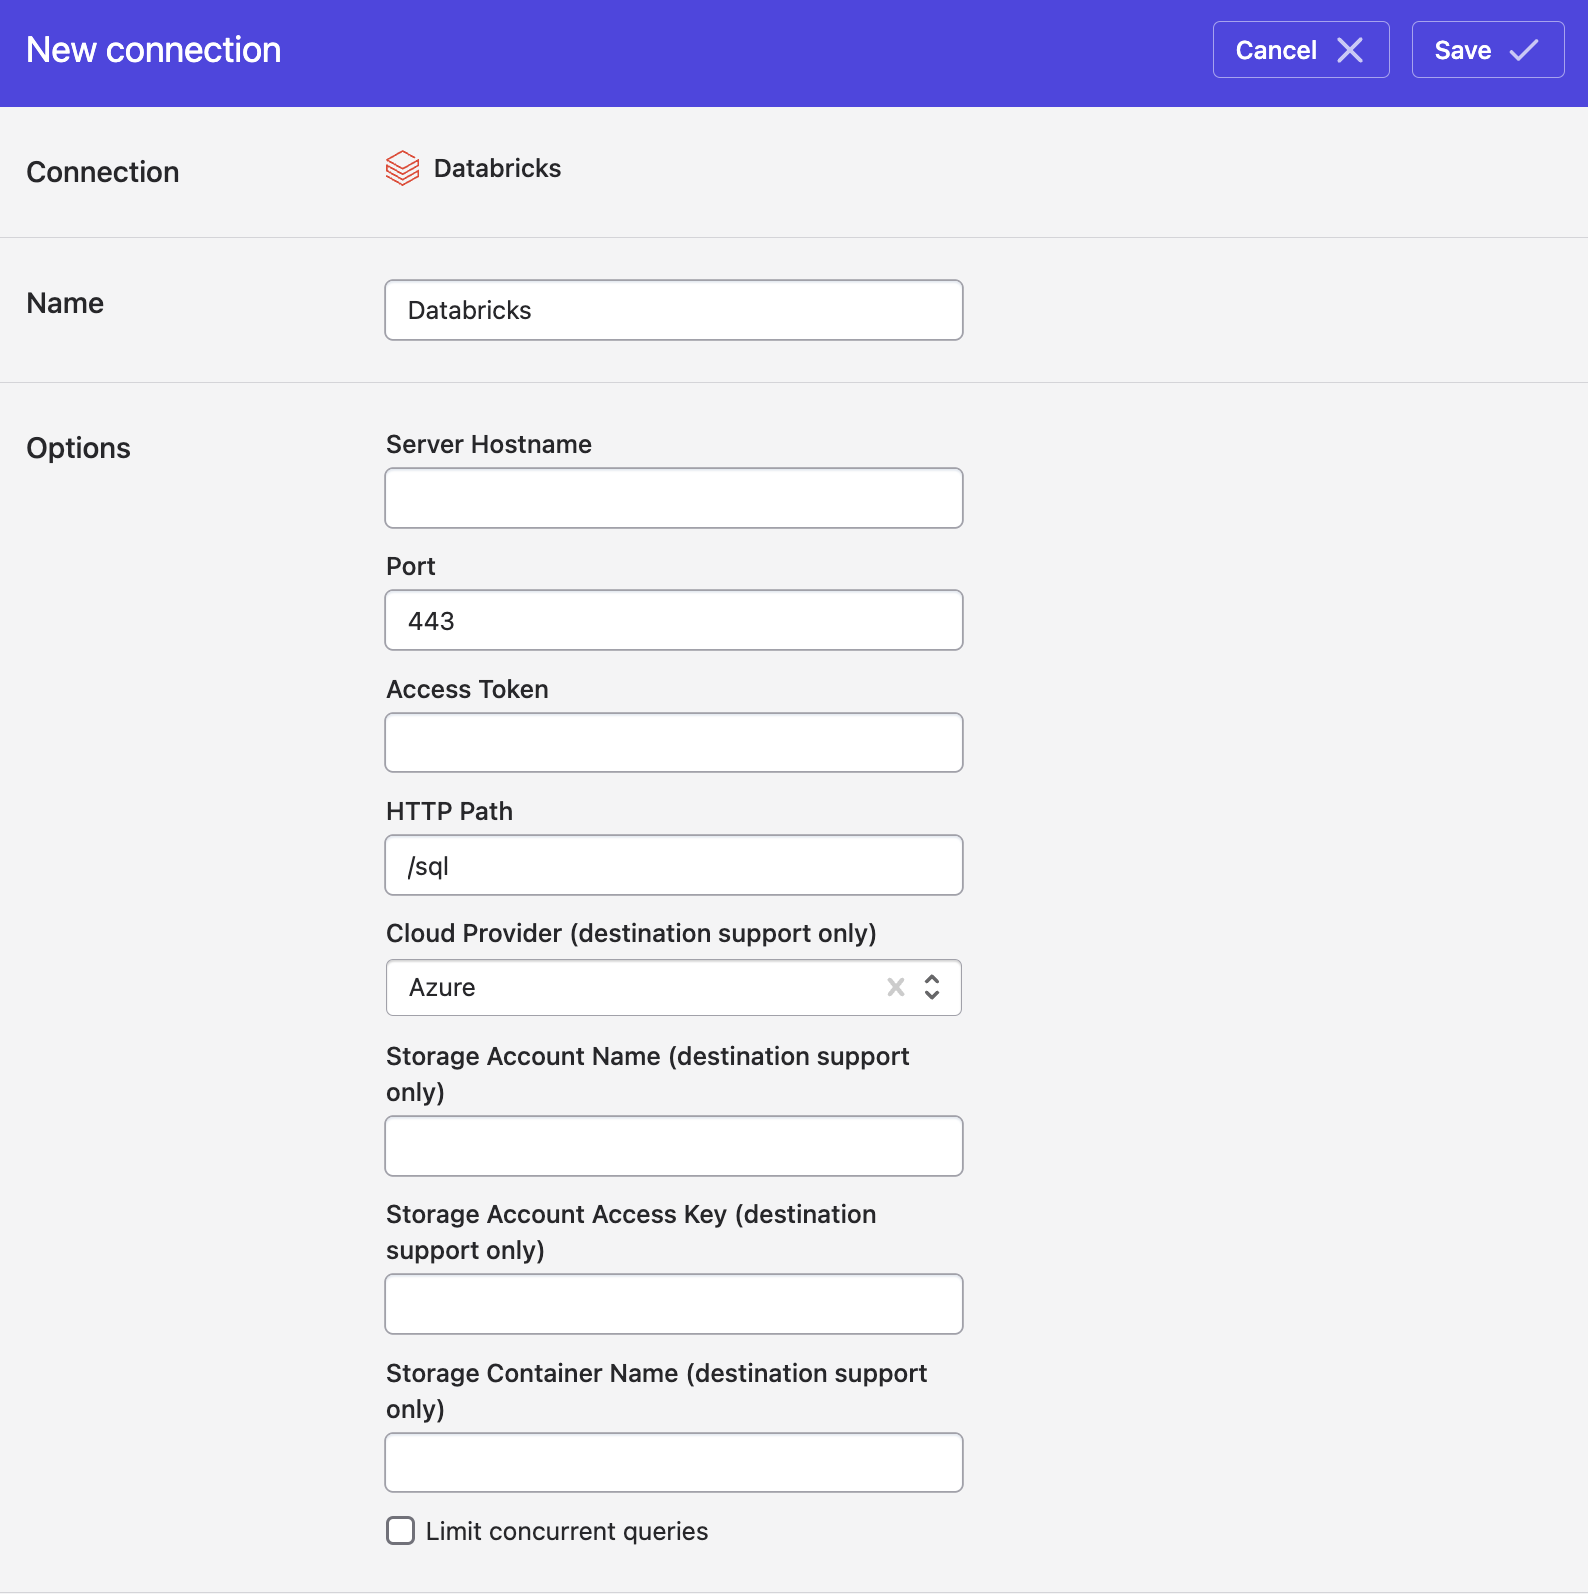
To enable Polytomic to write to your Azure Databricks cluster, you'll need to provide an Azure Storage container for us to stage data in.
Azure Storage Account TypeDatabricks requires that your Azure storage account is Data Lake Gen2 compatible. For this reason, it is recommended you create a new storage account/container for Polytomic to use. When creating a new storage account, enable the "Hierarchical Namespaces" feature on the Advanced setting tab.
You can read more about creating or migrating existing accounts on the Azure Support Portal.
You will need to enter the following values in Polytomic:
- Storage account name - the account name that contains the container Polytomic will write to.
- Storage account access key - the access key associated with the storage account.
- Storage container name - the container that Polytomic will write to.
If you connect to Databricks through an SSH tunnel, tick Use SSH for cloud storage bucket to also route uploads to the Azure storage account through the tunnel.
Modifying table retention policy
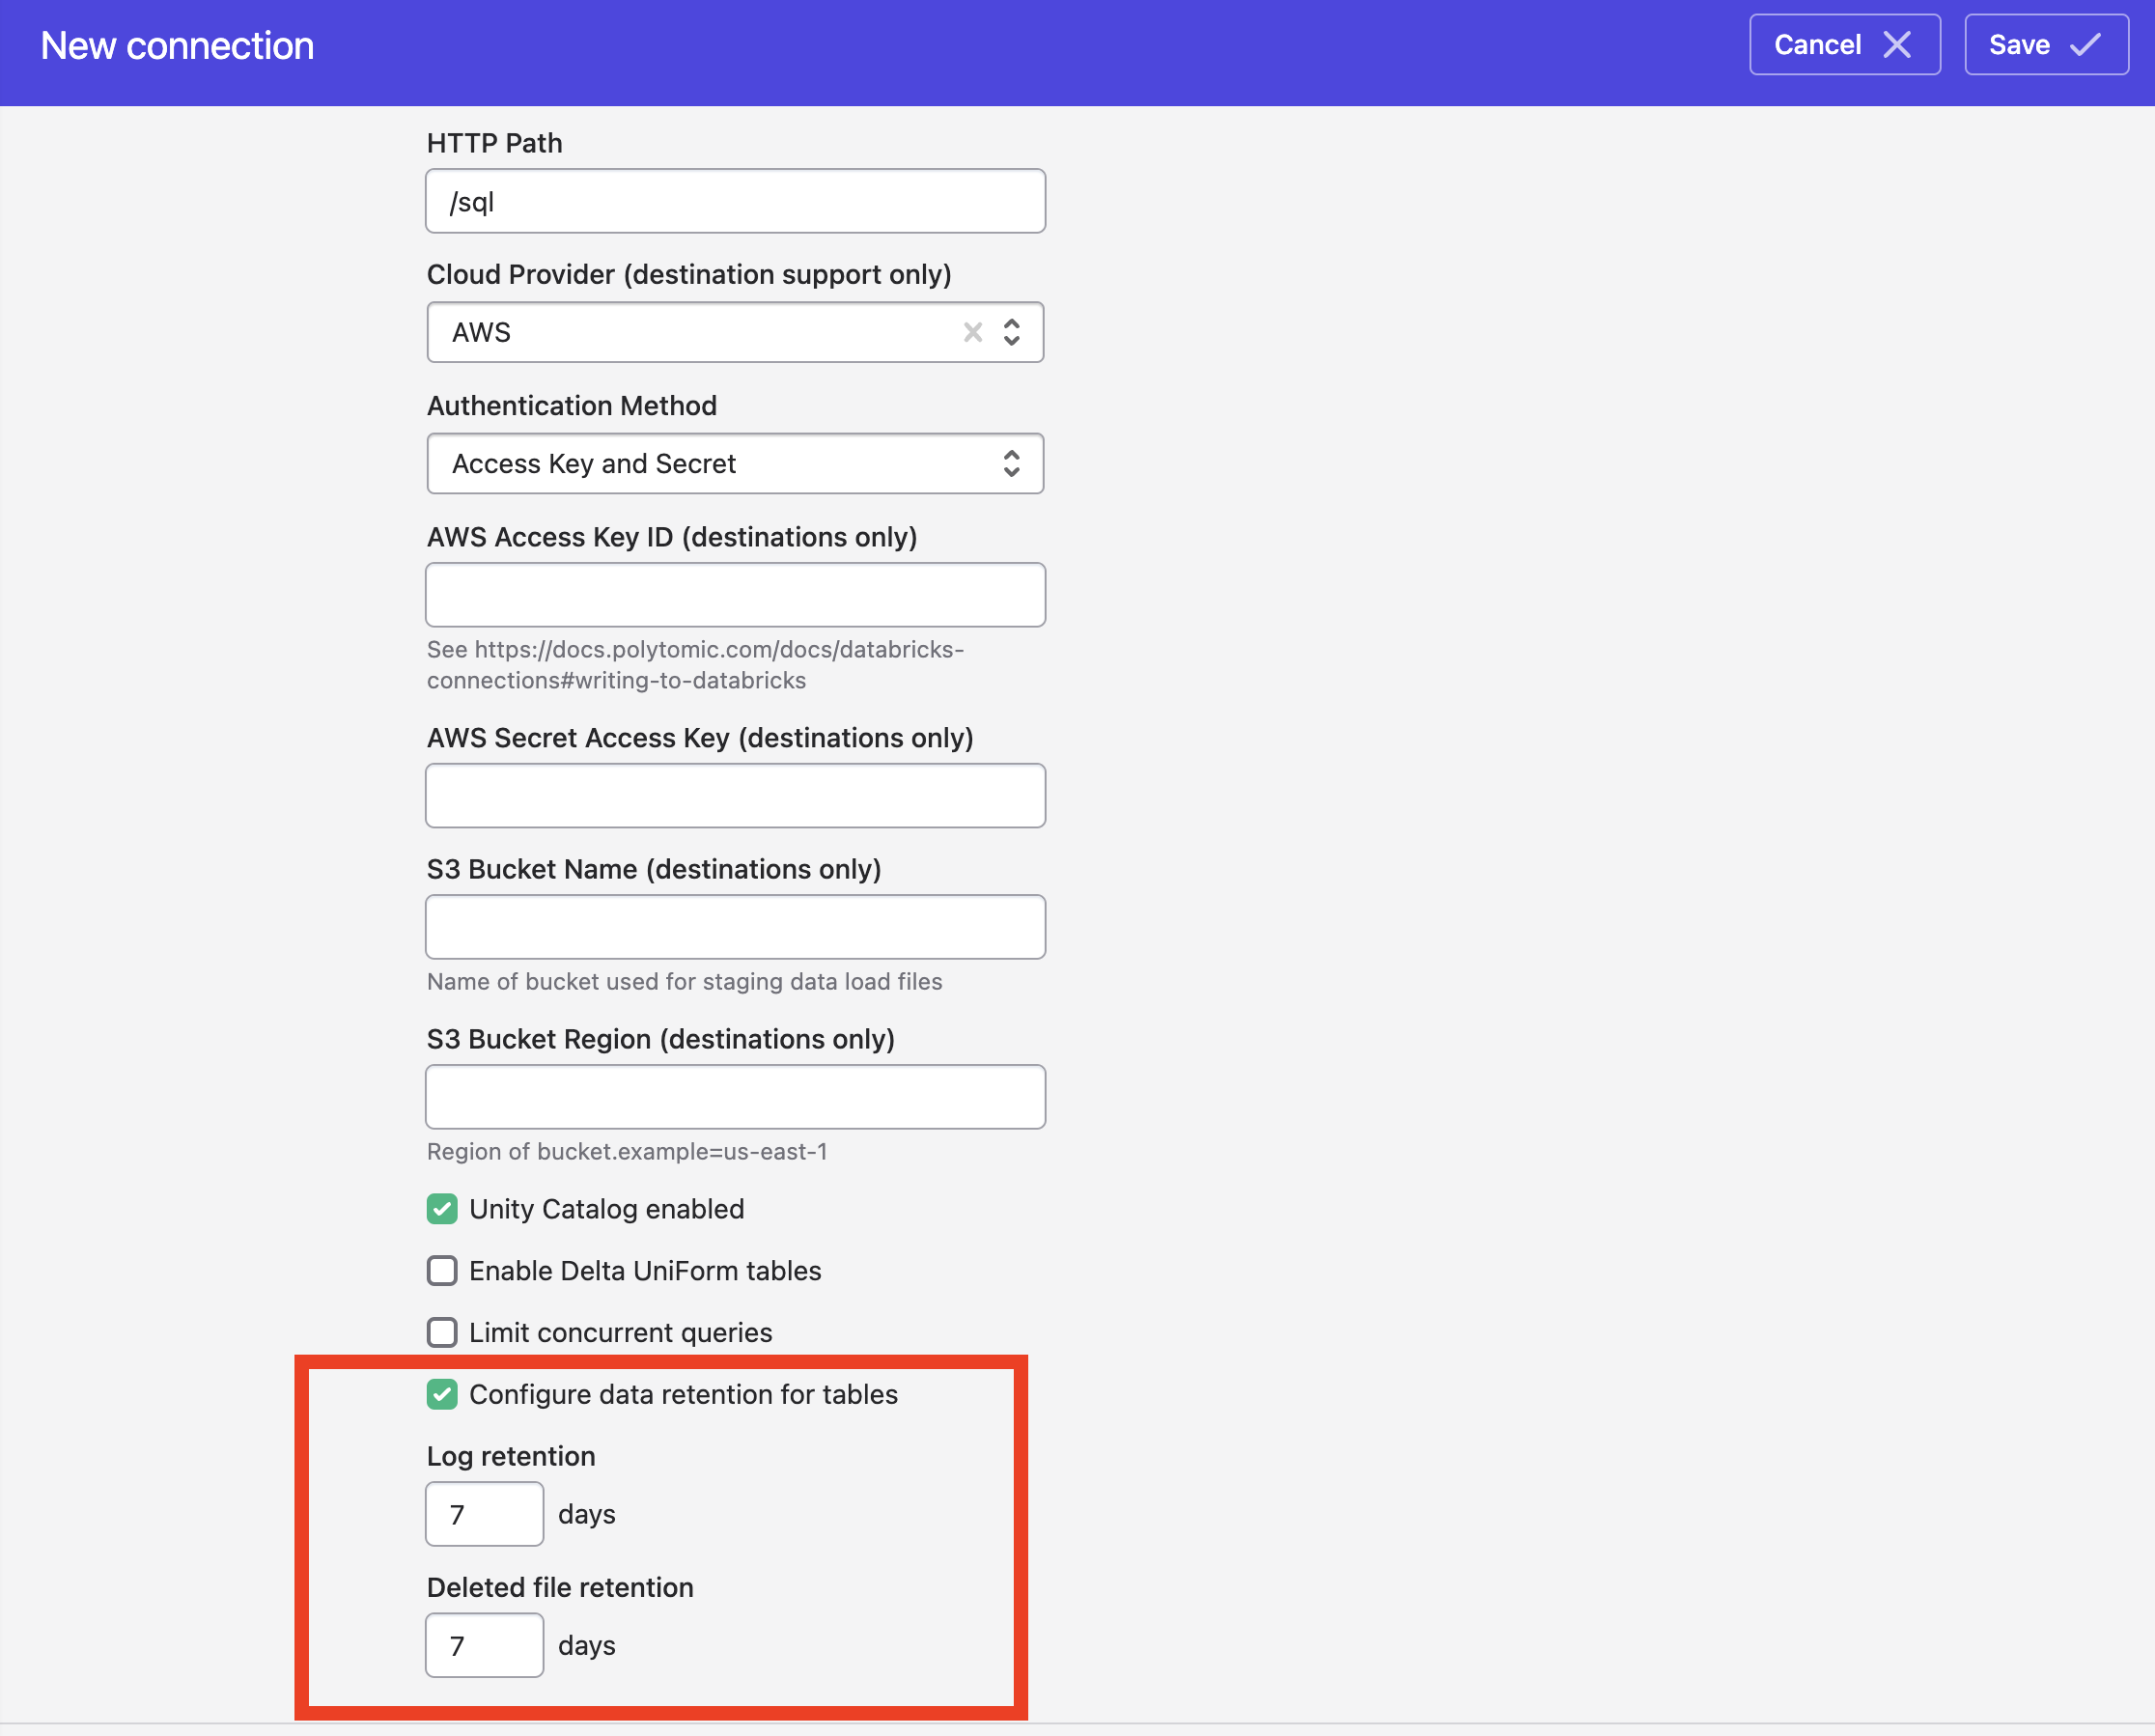
When syncing to Databricks on AWS using Polytomic's bulk syncs (i.e. ELT workloads), you can override the default Databricks table retention period by turning on the Configure data retention for tables setting at the bottom of your Databricks connection configuration:
Per-sync table retention policy
You can override the global retention policy per bulk sync by going to Advanced settings at the bottom of your bulk sync configuration and turning on the Configure data retention for tables setting:
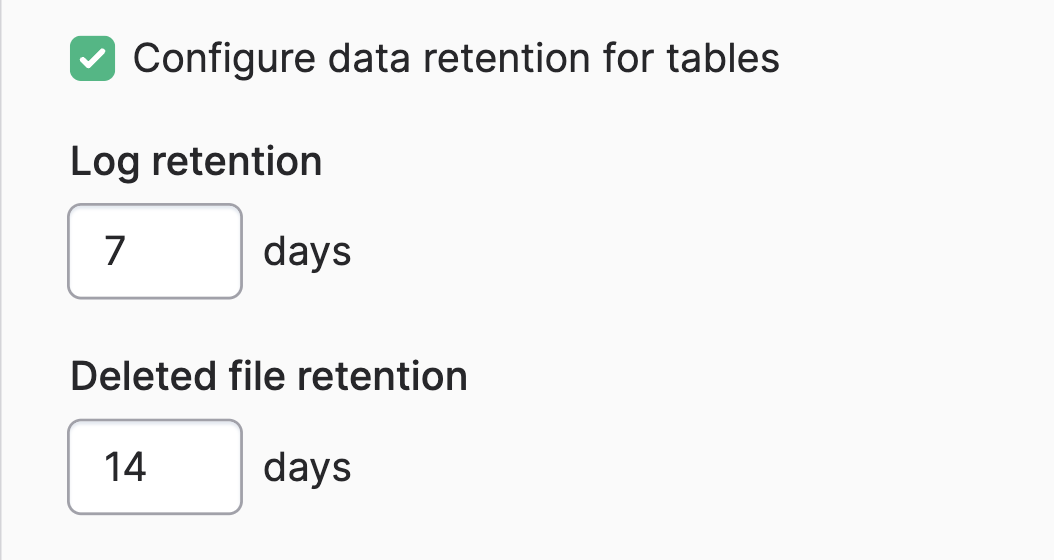
This will override whatever you have set in your Polytomic Databricks connection config.
Advanced: limiting concurrent queries on Databricks
You can choose to limit the number of concurrent queries Polytomic issues on Databricks by turning on the Limit concurrent queries option. You can then enter an integer limit of concurrent queries that Polytomic can issue:
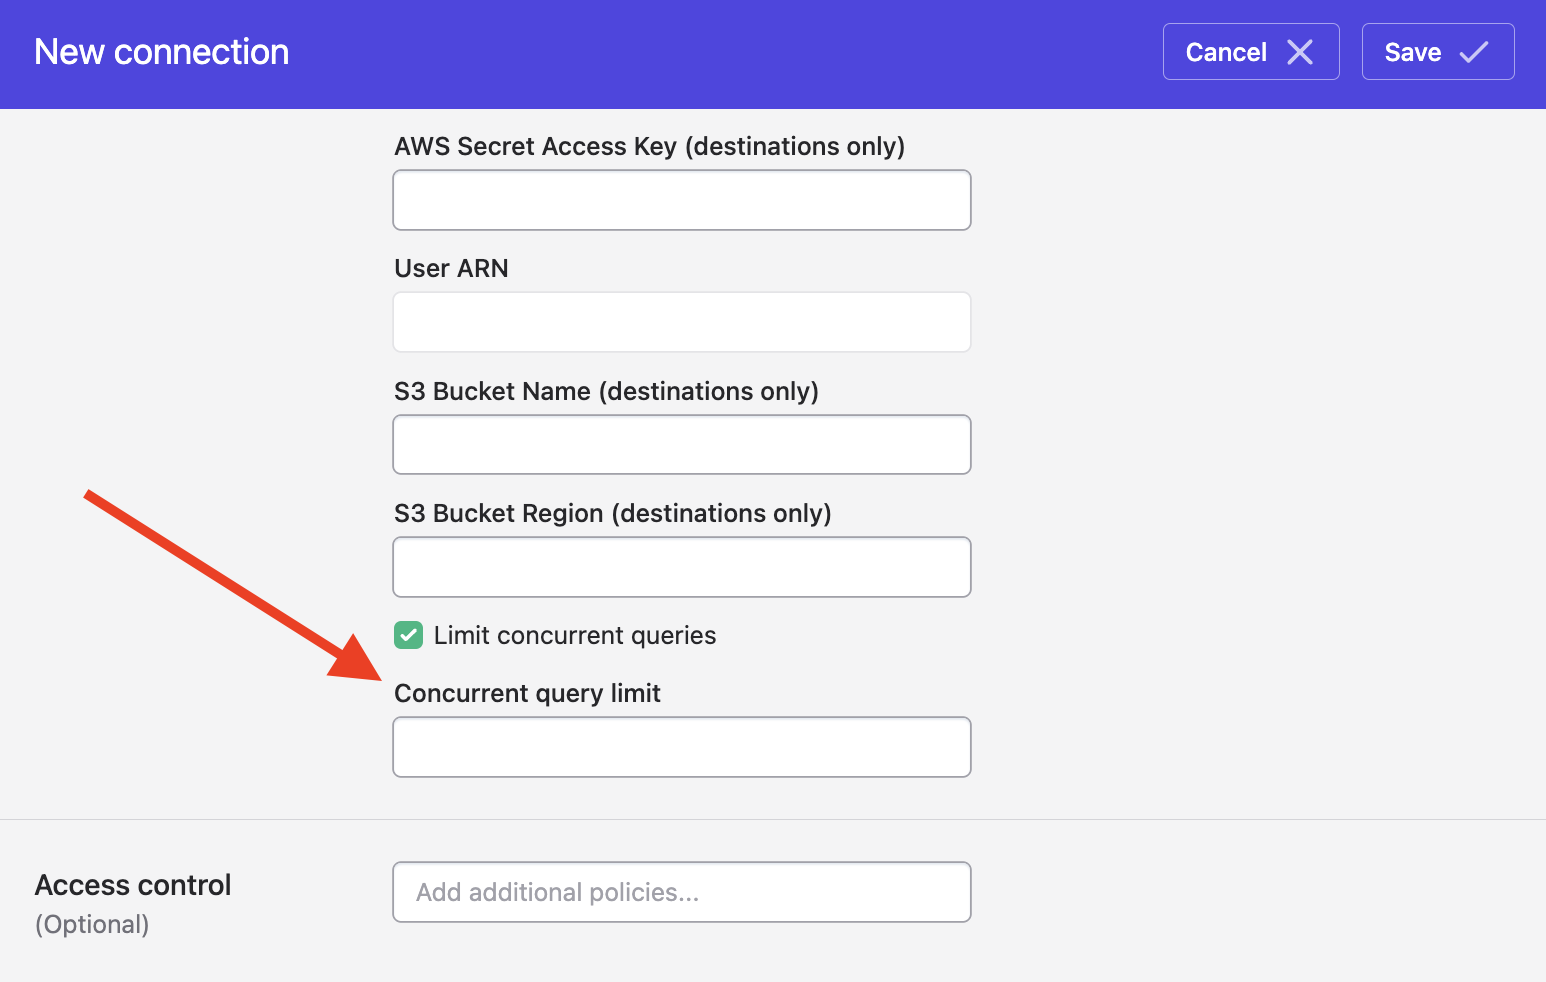
Unless you have a good reason for setting this, you should leave the option unset. During your operation of Polytomic, there are a couple of signs that would indicate the need to set a limit:
- An occasional
failed to execute query: Invalid OperationHandleerror from your Databricks cluster while Polytomic is running. - Any variance in sync running times when writing data to Databricks, where occasionally a sync takes much longer than usual.
Both are symptoms of Polytomic hitting your cluster's capacity for concurrency. The way to get around this is to turn on this option, thus limiting the number of concurrent queries Polytomic issues against your Databricks cluster.
Delta UniForm tables
Tick Enable Delta UniForm tables to have Polytomic create its destination tables with Delta UniForm enabled. Iceberg clients can then also read them as Iceberg tables. UniForm tables don't support partition keys.
Writing to external tables
If you'd like to write your destination tables to an external location that you've already set up within Databricks, you can specify this in Step 1 of your Polytomic Bulk Sync configuration:
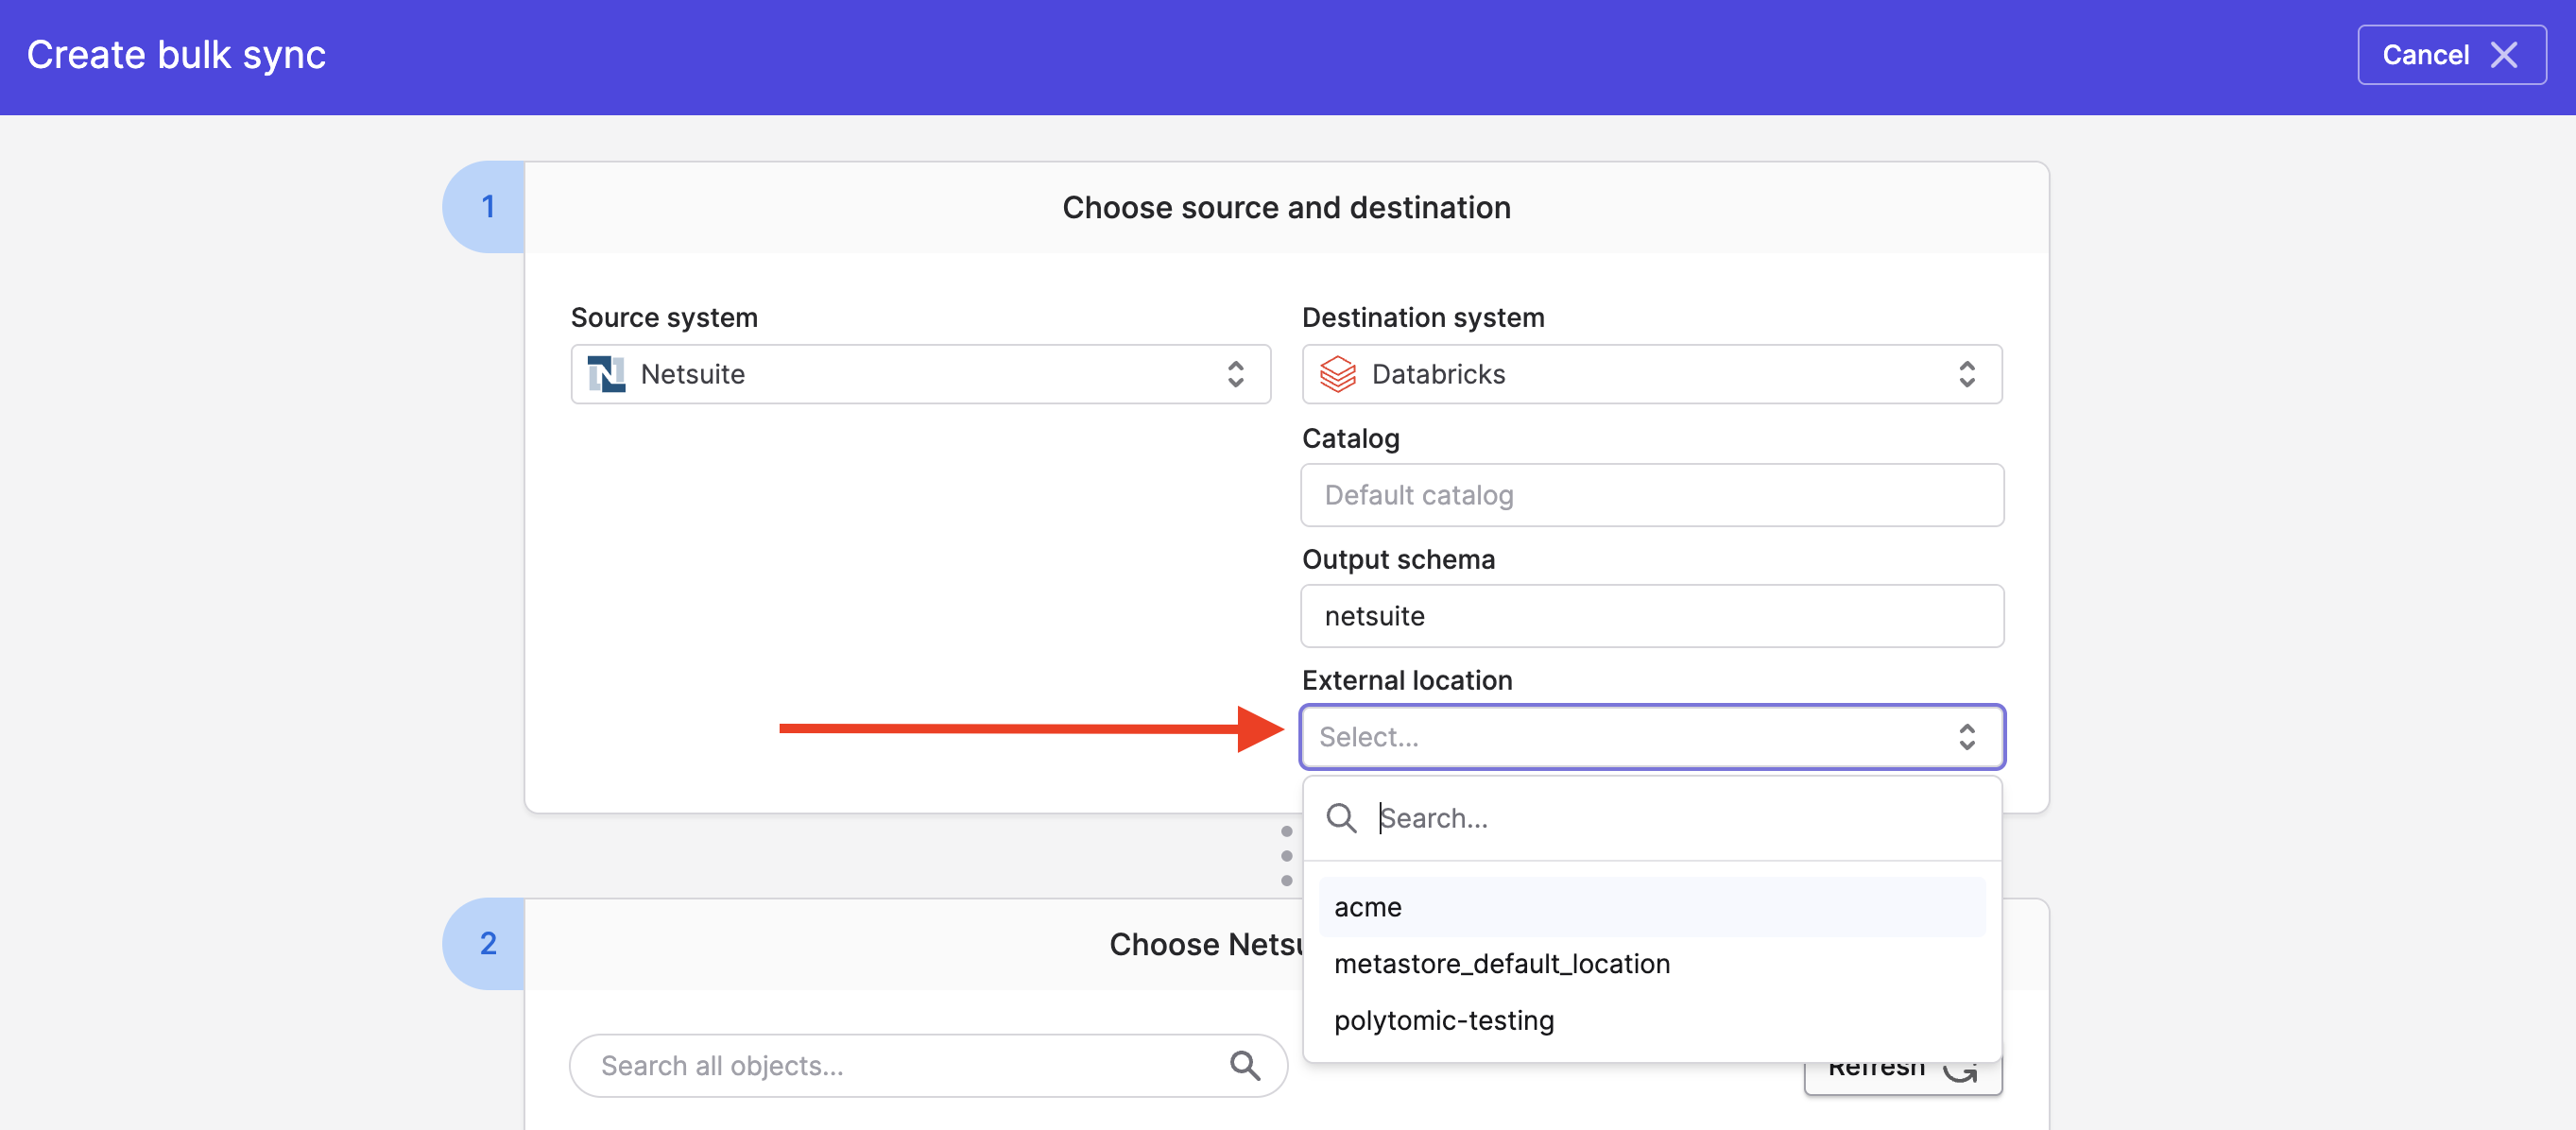
Not the same as the staging bucket credentialThis External location field controls where your destination tables are written. It does not govern how Databricks reads Polytomic's staging bucket. When using IAM role authentication, Databricks still needs a Storage Credential or a Unity Catalog External Location covering the staging bucket to read staged data — see IAM role authentication to Databricks AWS staging buckets.
Databricks permissions
The specific Databricks permissions required vary based on whether you're reading or writing data, and if you're writing, whether you're using an external location.
Reading from Databricks
The following permissions are required to read from Databricks.
USE CATALOGon any catalogs you wish to access.USE SCHEMAon any schemas you wish to access.SELECTon any tables you wish to access.CAN USEon the SQL warehouse (workspace permission, not a Unity Catalog privilege).
For example, for a service principal whose application ID is <sp-application-id>:
GRANT USE CATALOG ON CATALOG my_catalog TO `<sp-application-id>`;
GRANT USE SCHEMA, SELECT ON SCHEMA my_catalog.my_schema TO `<sp-application-id>`;
Writing to Databricks
In addition to the permissions required for reading, the following permissions are required to write to Databricks.
CREATE SCHEMAon catalogs you are writing to.CREATE TABLEon any existing schemas you are writing to.
GRANT USE CATALOG, CREATE SCHEMA ON CATALOG my_catalog TO `<sp-application-id>`;
GRANT USE SCHEMA, CREATE TABLE ON SCHEMA my_catalog.my_schema TO `<sp-application-id>`;
Polytomic creates new schemas and tables as needed, and its user owns them. We recommend this setup. Polytomic loads data through staging tables that it renames into place. It also alters, clusters, vacuums, and replaces its destination tables as your source changes. These operations require ownership of the table, or the MANAGE privilege on it in addition to MODIFY and SELECT. If Polytomic must write to an existing table it didn't create, transfer ownership to Polytomic or grant those privileges:
GRANT MANAGE, MODIFY, SELECT ON TABLE my_catalog.my_schema.my_table TO `<sp-application-id>`;If you are writing to tables stored in an external location, the following additional permissions are required.
CREATE EXTERNAL TABLEon the external location and associated storage credential.READ FILESon the external location.READ VOLUMEon the associated volume, if any.
Updated 5 days ago